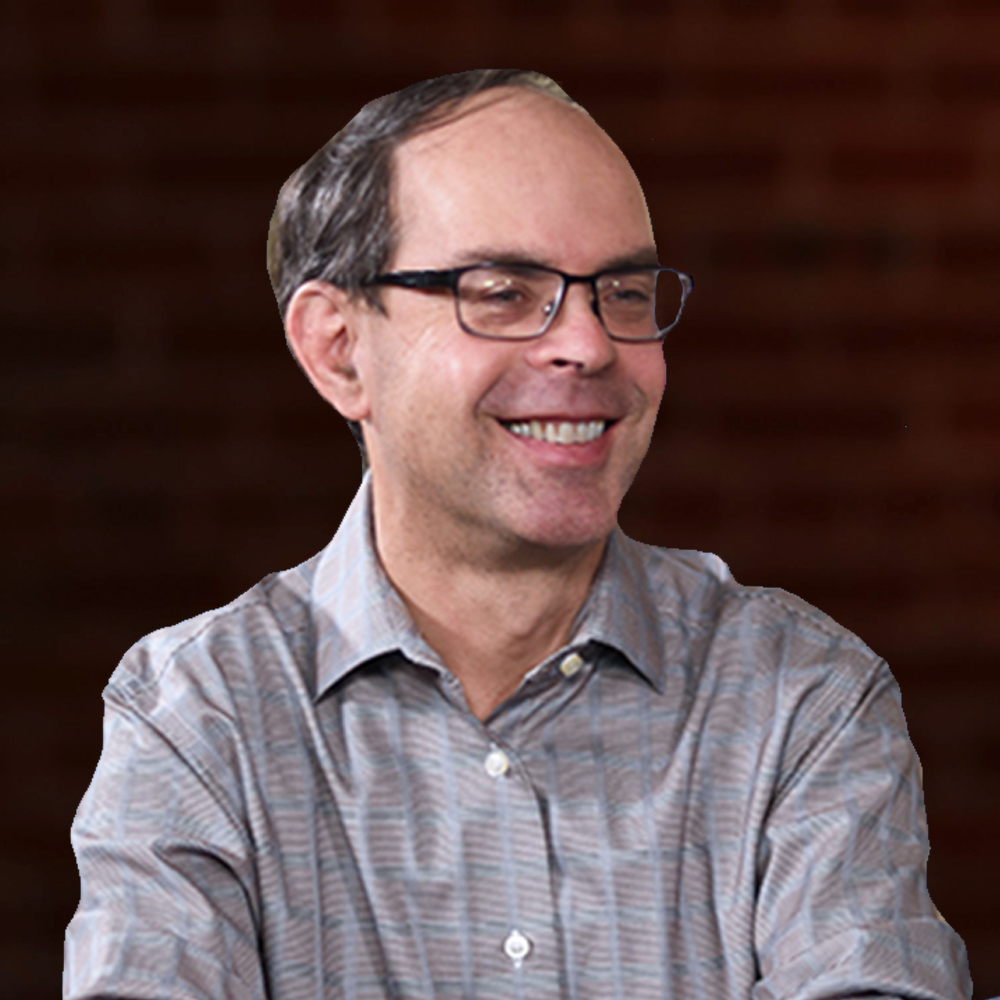
Reynold Xin, Databricks, at #Spark Summit on #theCUBE
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/19/spark-doubles-down-streaming-data-warehousing-deep-learning-sparksummit/
Spark doubles down on streaming, data warehousing and deep learning
The Apache Spark community has been wrestling with a wide range of big data challenges in information technology, and Databricks Inc. (which was founded by Spark’s creators), is taking steps to address the enterprise need for machine learning and speedier data processing.
“Rather than giving people the fish, you give them the tools to fish,” said Reynold Xin (pictured), chief architect and co-founder at Databricks.
Xin stopped by theCUBE, SiliconANGLE’s mobile livestreaming studio, and answered questions from hosts David Goad (@davidgoad) and George Gilbert (@ggilbert41), during this year’s Spark Summit 2017 in San Francisco, California. They discussed changes for the Spark platform, the role of storage systems in analytics and the next big challenge for the Spark community. (* Disclosure below.)
Deep learning is a priority
One of the tools announced by Databricks during the Spark Summit was Deep Learning Pipelines, an open-source library designed to give users the ability to create neural networks for data processing. “We’re hoping to democratize deep learning,” Xin said.
Seeking to dramatically speed-up data processing, Databricks has also blended a Structured Streaming tool into its enterprise portfolio. Databricks customers processed 3 trillion records last month using Structured Streaming and brought latency down to the three millisecond range, according to Xin.
Databricks is also working to improve the visibility and what Xin termed “debug-ability” of big data jobs. By improving the performance and capability of data warehousing features in Spark, this will also increase job processing speed, he added.
While storage systems have “matured” and Spark can work effectively with a variety of them, Xin is not prepared to include storage in an analytical role just yet. “It doesn’t make sense to build storage systems for analytics at this point,” said the Databricks co-founder.
Despite the release of new enhancements, the challenge for the Spark community will continue to be finding ways to make data management and deep learning tools easier to use. “The bar to entry is very high for these tools. It’s what we focus on a lot at Databricks,” Xin concluded.
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Register For Spark Summit 2017 | San Francisco
Please fill out the information below. You will recieve an email with a verification link confirming your registration. Click the link to automatically sign into the site.
You’re almost there!
We just sent you a verification email. Please click the verification button in the email. Once your email address is verified, you will have full access to all event content for Spark Summit 2017 | San Francisco.
I want my badge and interests to be visible to all attendees.
Checking this box will display your presense on the attendees list, view your profile and allow other attendees to contact you via 1-1 chat. Read the Privacy Policy. At any time, you can choose to disable this preference.
Select your Interests!
add
Upload your photo
Uploading..
OR
Connect via Twitter
Connect via Linkedin
EDIT PASSWORD
Share
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Sign in to gain access to Spark Summit 2017 | San Francisco
Please sign in with LinkedIn to continue to Spark Summit 2017 | San Francisco. Signing in with LinkedIn ensures a professional environment.
Are you sure you want to remove access rights for this user?
Details
Manage Access
email address
Community Invitation
Reynold Xin | Spark Summit 2017
Reynold Xin, Databricks, at #Spark Summit on #theCUBE
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/19/spark-doubles-down-streaming-data-warehousing-deep-learning-sparksummit/
Spark doubles down on streaming, data warehousing and deep learning
The Apache Spark community has been wrestling with a wide range of big data challenges in information technology, and Databricks Inc. (which was founded by Spark’s creators), is taking steps to address the enterprise need for machine learning and speedier data processing.
“Rather than giving people the fish, you give them the tools to fish,” said Reynold Xin (pictured), chief architect and co-founder at Databricks.
Xin stopped by theCUBE, SiliconANGLE’s mobile livestreaming studio, and answered questions from hosts David Goad (@davidgoad) and George Gilbert (@ggilbert41), during this year’s Spark Summit 2017 in San Francisco, California. They discussed changes for the Spark platform, the role of storage systems in analytics and the next big challenge for the Spark community. (* Disclosure below.)
Deep learning is a priority
One of the tools announced by Databricks during the Spark Summit was Deep Learning Pipelines, an open-source library designed to give users the ability to create neural networks for data processing. “We’re hoping to democratize deep learning,” Xin said.
Seeking to dramatically speed-up data processing, Databricks has also blended a Structured Streaming tool into its enterprise portfolio. Databricks customers processed 3 trillion records last month using Structured Streaming and brought latency down to the three millisecond range, according to Xin.
Databricks is also working to improve the visibility and what Xin termed “debug-ability” of big data jobs. By improving the performance and capability of data warehousing features in Spark, this will also increase job processing speed, he added.
While storage systems have “matured” and Spark can work effectively with a variety of them, Xin is not prepared to include storage in an analytical role just yet. “It doesn’t make sense to build storage systems for analytics at this point,” said the Databricks co-founder.
Despite the release of new enhancements, the challenge for the Spark community will continue to be finding ways to make data management and deep learning tools easier to use. “The bar to entry is very high for these tools. It’s what we focus on a lot at Databricks,” Xin concluded.
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)