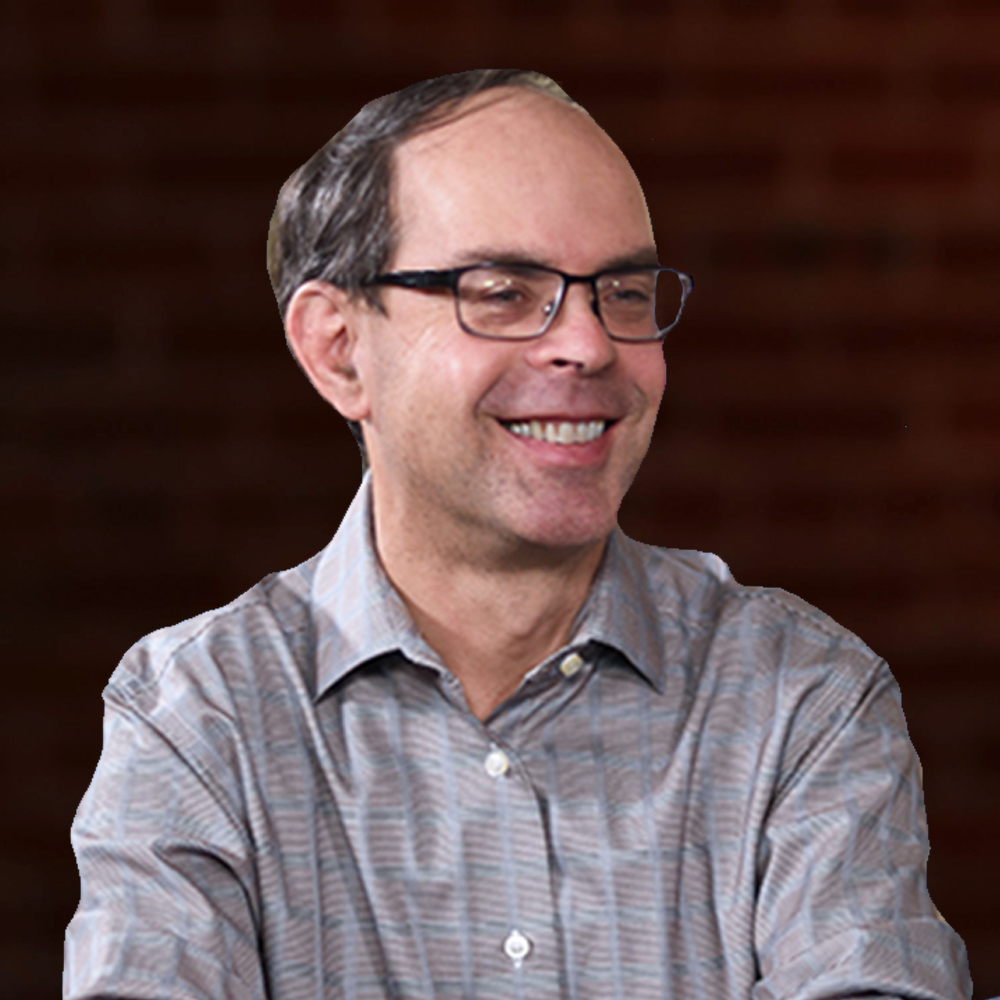
Rob Lantz, Novetta, at Spark Summit 2017
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/25/automating-entity-recognition-extraction-and-resolution-sparksummit/
Automating entity recognition, extraction and resolution
Identifying and extracting relevant entities from masses of stored data is a complex and tedious task. Advanced analytics company Novetta Solutions LLC is using the functionality of Databricks Inc., a cloud-based data management service, to speed up and even automate the process.
“The beauty of what Databricks promises is the ability to save a lot of the time that we would spend doing the ‘nug’ work on cluster management,” said Rob Lantz (pictured), director of predictive analytics at Novetta. “We’re getting into the machine learning space as far as entity extraction and resolution and recognition, because more and more data is unstructured.”
Lantz explained that “getting a proof set that’s already tagged” is the key. He spoke to George Gilbert (@ggilbert41) and David Goad (@davidgoad), co-hosts of theCUBE, SiliconANGLE Media’s mobile livestreaming studio, during this year’s Spark Summit event in San Francisco, California. (* Disclosure below.)
Removing the human from the loop
Novetta already has products that go in and do concept tagging across multiple languages. Once a training set has been established, scaling is relatively simple, Lantz explained. The ultimate goal is to remove the human from the loop and have automated entity extraction: “Pulling every name out, every phone number out, every address out …” Lantz said.
Training machine learning to automatically extract entities from unstructured data is a future goal, but Novetta is already seeing benefits from Spark. As well as increased speed and customers are able to build on Novetta’s solution to quantify profiles to their own specifications.
“They take the resolve data, and that gets resolved nightly, or even hourly, and they build those profiles themselves for their own purpose,” Lantz added. Once the data is harmonized, it can go into any number of places in the cloud or on-prem.
Lantz’s wish list for the Spark community is simple: A more robust MLlib, Spark’s scalable machine learning library. “Then I think everything else is there, frankly. We are very excited about the platform and the stack that comes with it,” he concluded.
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Register For Spark Summit 2017 | San Francisco
Please fill out the information below. You will recieve an email with a verification link confirming your registration. Click the link to automatically sign into the site.
You’re almost there!
We just sent you a verification email. Please click the verification button in the email. Once your email address is verified, you will have full access to all event content for Spark Summit 2017 | San Francisco.
I want my badge and interests to be visible to all attendees.
Checking this box will display your presense on the attendees list, view your profile and allow other attendees to contact you via 1-1 chat. Read the Privacy Policy. At any time, you can choose to disable this preference.
Select your Interests!
add
Upload your photo
Uploading..
OR
Connect via Twitter
Connect via Linkedin
EDIT PASSWORD
Share
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Sign in to gain access to Spark Summit 2017 | San Francisco
Please sign in with LinkedIn to continue to Spark Summit 2017 | San Francisco. Signing in with LinkedIn ensures a professional environment.
Are you sure you want to remove access rights for this user?
Details
Manage Access
email address
Community Invitation
Rob Lantz, Novetta | Spark Summit 2017
Rob Lantz, Novetta, at Spark Summit 2017
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/25/automating-entity-recognition-extraction-and-resolution-sparksummit/
Automating entity recognition, extraction and resolution
Identifying and extracting relevant entities from masses of stored data is a complex and tedious task. Advanced analytics company Novetta Solutions LLC is using the functionality of Databricks Inc., a cloud-based data management service, to speed up and even automate the process.
“The beauty of what Databricks promises is the ability to save a lot of the time that we would spend doing the ‘nug’ work on cluster management,” said Rob Lantz (pictured), director of predictive analytics at Novetta. “We’re getting into the machine learning space as far as entity extraction and resolution and recognition, because more and more data is unstructured.”
Lantz explained that “getting a proof set that’s already tagged” is the key. He spoke to George Gilbert (@ggilbert41) and David Goad (@davidgoad), co-hosts of theCUBE, SiliconANGLE Media’s mobile livestreaming studio, during this year’s Spark Summit event in San Francisco, California. (* Disclosure below.)
Removing the human from the loop
Novetta already has products that go in and do concept tagging across multiple languages. Once a training set has been established, scaling is relatively simple, Lantz explained. The ultimate goal is to remove the human from the loop and have automated entity extraction: “Pulling every name out, every phone number out, every address out …” Lantz said.
Training machine learning to automatically extract entities from unstructured data is a future goal, but Novetta is already seeing benefits from Spark. As well as increased speed and customers are able to build on Novetta’s solution to quantify profiles to their own specifications.
“They take the resolve data, and that gets resolved nightly, or even hourly, and they build those profiles themselves for their own purpose,” Lantz added. Once the data is harmonized, it can go into any number of places in the cloud or on-prem.
Lantz’s wish list for the Spark community is simple: A more robust MLlib, Spark’s scalable machine learning library. “Then I think everything else is there, frankly. We are very excited about the platform and the stack that comes with it,” he concluded.
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)