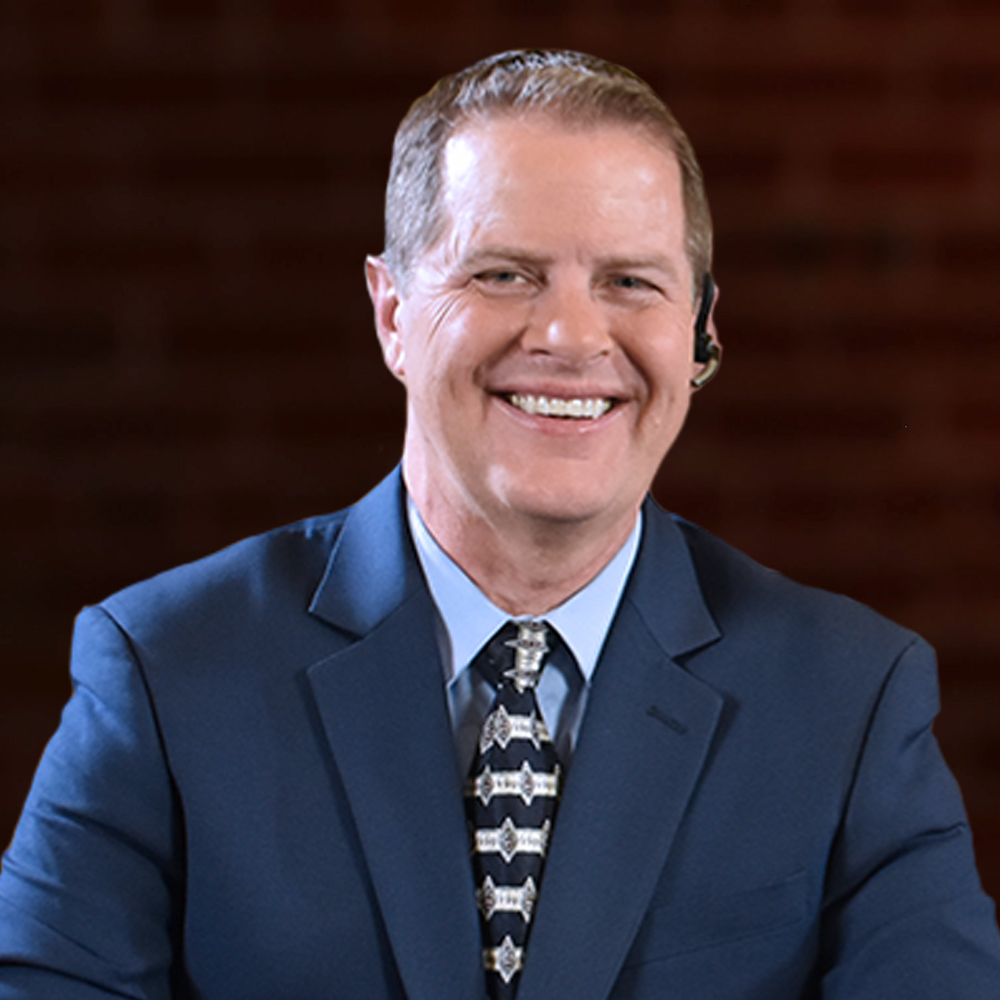
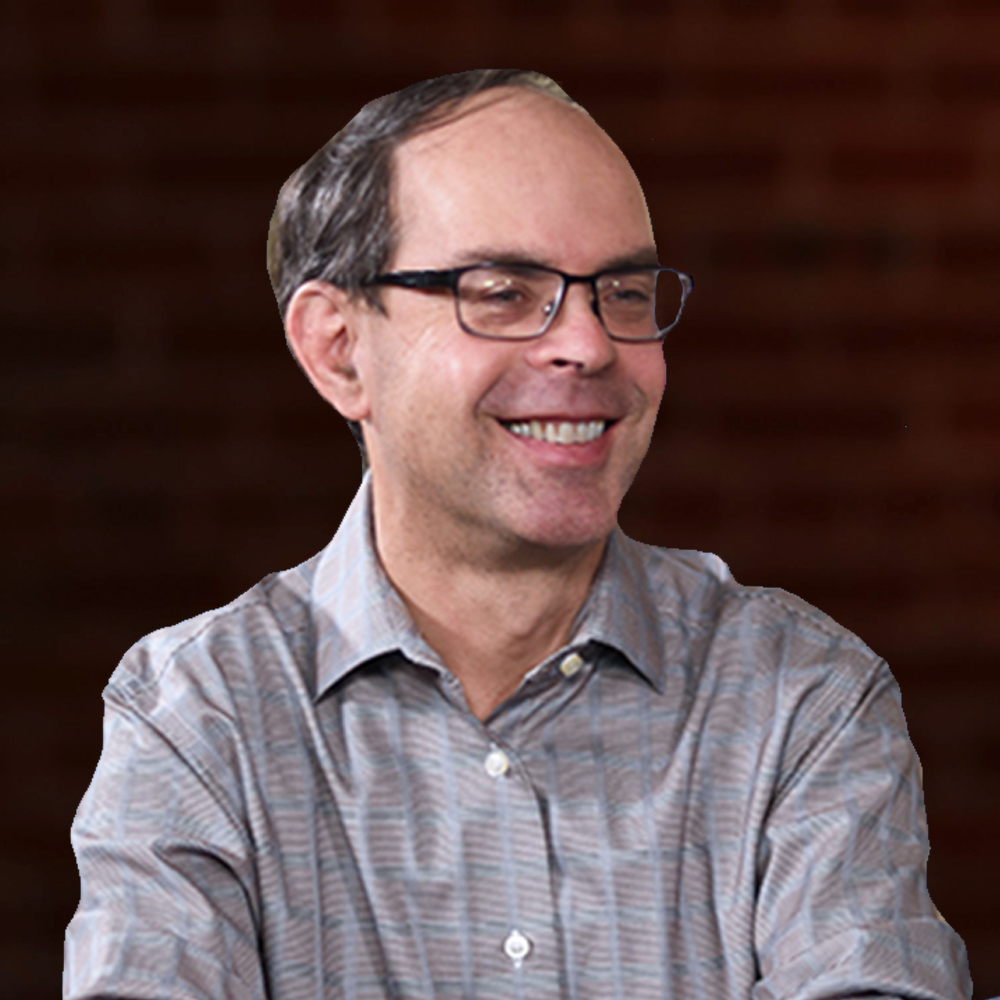
Clarke Patterson from Confluent joins CUBE hosts David Goad & George Gilbert are live from Spark Summit 2017 at the Moscone West in San Francisco CA
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/20/confluent-makes-kafka-easier-cloud-data-powers-small-business-sparksummit/
Confluent makes Kafka easier in the cloud, grants new data powers to small business
Where data processing is concerned, speed is life. Companies can ship off some workloads to batch processing, but they need to process the critical stuff in real-time while a customer or system interaction is happening. Not all companies have the resources to make this happen, however. That’s where big data company Confluent Inc. and distributed data streaming platform Apache Kafka step in.
“We’ve done a lot to enable customers to adopt Confluent in the cloud,” said Clarke Patterson (pictured), the former senior director of product marketing at Confluent.
Patterson was speaking to David Goad (@davidgoad) and George Gilbert (@ggilbert41), co-hosts of theCUBE, SiliconANGLE’s mobile livestreaming studio, during this year’s Spark Summit in San Francisco, California. They discussed how Kafka, the open-source platform whose creators founded Confluent, can improve data processing. (* Disclosure below.)
Bringing the power of streaming data to the cloud
To boost its presence in the cloud, Confluent came up with a Confluent Cloud offering, which is a managed service of its Confluent platform. It fits a need for cloud-first or operations-starved companies who want to operationalize Kafka. The Confluent Cloud service allows users to apply Kafka with Confluent as the backstop.
Two recent advancements make this a valuable service, Patterson explained. One is Kafka’s new ability to connect and integrate large numbers of data producers and consumers as information flows through. The second is a Kafka API that powers streaming processing and is built into the system. This allows companies to perform lightweight data transformations while the data is moving.
By comparison, data integration used to be about collecting a lot of data from a bunch of systems, transforming it and then shipping it off to some other place in the business. Now speed is vital, both for data and application integration, Patterson stated. For many workloads, Kafka can provide both speed and the capacity to process large amounts of data in real-time.
“We see a lot of people that are going into microservices-oriented architecture,” Patterson said. That means moving away from monolithic applications that are hard to change. By splitting up into smaller, functional components, they can then integrate these microservices much faster. Kafka provides a way to connect all those pieces, he concluded
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Register For Spark Summit 2017 | San Francisco
Please fill out the information below. You will recieve an email with a verification link confirming your registration. Click the link to automatically sign into the site.
You’re almost there!
We just sent you a verification email. Please click the verification button in the email. Once your email address is verified, you will have full access to all event content for Spark Summit 2017 | San Francisco.
I want my badge and interests to be visible to all attendees.
Checking this box will display your presense on the attendees list, view your profile and allow other attendees to contact you via 1-1 chat. Read the Privacy Policy. At any time, you can choose to disable this preference.
Select your Interests!
add
Upload your photo
Uploading..
OR
Connect via Twitter
Connect via Linkedin
EDIT PASSWORD
Share
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Sign in to gain access to Spark Summit 2017 | San Francisco
Please sign in with LinkedIn to continue to Spark Summit 2017 | San Francisco. Signing in with LinkedIn ensures a professional environment.
Are you sure you want to remove access rights for this user?
Details
Manage Access
email address
Community Invitation
Clarke Patterson | Spark Summit 2017
Clarke Patterson from Confluent joins CUBE hosts David Goad & George Gilbert are live from Spark Summit 2017 at the Moscone West in San Francisco CA
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/20/confluent-makes-kafka-easier-cloud-data-powers-small-business-sparksummit/
Confluent makes Kafka easier in the cloud, grants new data powers to small business
Where data processing is concerned, speed is life. Companies can ship off some workloads to batch processing, but they need to process the critical stuff in real-time while a customer or system interaction is happening. Not all companies have the resources to make this happen, however. That’s where big data company Confluent Inc. and distributed data streaming platform Apache Kafka step in.
“We’ve done a lot to enable customers to adopt Confluent in the cloud,” said Clarke Patterson (pictured), the former senior director of product marketing at Confluent.
Patterson was speaking to David Goad (@davidgoad) and George Gilbert (@ggilbert41), co-hosts of theCUBE, SiliconANGLE’s mobile livestreaming studio, during this year’s Spark Summit in San Francisco, California. They discussed how Kafka, the open-source platform whose creators founded Confluent, can improve data processing. (* Disclosure below.)
Bringing the power of streaming data to the cloud
To boost its presence in the cloud, Confluent came up with a Confluent Cloud offering, which is a managed service of its Confluent platform. It fits a need for cloud-first or operations-starved companies who want to operationalize Kafka. The Confluent Cloud service allows users to apply Kafka with Confluent as the backstop.
Two recent advancements make this a valuable service, Patterson explained. One is Kafka’s new ability to connect and integrate large numbers of data producers and consumers as information flows through. The second is a Kafka API that powers streaming processing and is built into the system. This allows companies to perform lightweight data transformations while the data is moving.
By comparison, data integration used to be about collecting a lot of data from a bunch of systems, transforming it and then shipping it off to some other place in the business. Now speed is vital, both for data and application integration, Patterson stated. For many workloads, Kafka can provide both speed and the capacity to process large amounts of data in real-time.
“We see a lot of people that are going into microservices-oriented architecture,” Patterson said. That means moving away from monolithic applications that are hard to change. By splitting up into smaller, functional components, they can then integrate these microservices much faster. Kafka provides a way to connect all those pieces, he concluded
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)