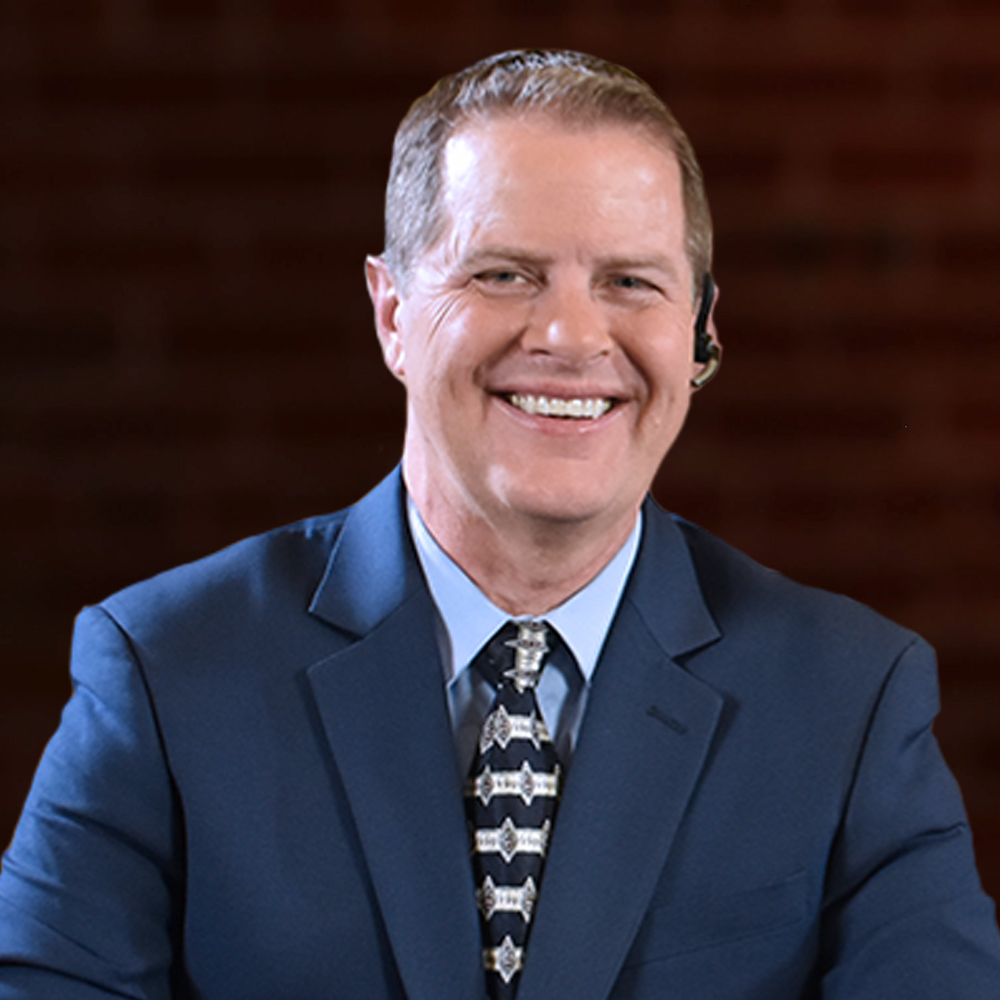
Matthew Hunt, Bloomberg, at Spark Summit 2017
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/25/could-apache-spark-become-a-universal-computation-engine-sparksummit/
Could Apache Spark become a universal computation engine?
Spark Summit keynotes are known for their surprises, and this year the stand-out changes were in data streaming, with sub-millisecond times predicted for some workloads. With multiple avenues open for potential success, the community is watching as Spark matures to fulfill the promise of what it could be: But does that promise include becoming a database?
Exploring the gap between theoretical possibilities and reality, Matthew Hunt (pictured) technologist at Bloomberg LP, discussed the maturation of Spark with George Gilbert (@ggilbert41) and David Goad (@davidgoad), co-hosts of theCUBE, SiliconANGLE Media’s mobile livestreaming studio, during this year’s Spark Summit event in San Francisco, California.
As a pioneer of streaming media, Bloomberg has a long history developing apps for news and finance and has developed its own relational database, ComDB2. “Everyone needs a database,” Hunt said, adding that most companies do not have the resources to develop their own. This leads to the question: Can Spark become a database?
Hunt believes that Spark has the promise to become a Universal Computation Engine. Describing a universal system as having distributed file store, database with transactional semantics, extensible analytics and the ability to stream data in, he asked, “how close can you come to that?”
Maturity means real-world use
Although the dream might be a universal system, the more practical question is how to make Spark and other databases work well together.
“If you have to master 5,000 skills and 200 different products, that’s a huge impediment for real-world usage,” said Hunt, who sees practical usage coalescing around a smaller set of options.
Hunt predicted that Apache Arrow, which powers columnar in-memory analytics, is about to explode because “it lets you connect these systems radically more efficiently in a standardized way.”
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Register For Spark Summit 2017 | San Francisco
Please fill out the information below. You will recieve an email with a verification link confirming your registration. Click the link to automatically sign into the site.
You’re almost there!
We just sent you a verification email. Please click the verification button in the email. Once your email address is verified, you will have full access to all event content for Spark Summit 2017 | San Francisco.
I want my badge and interests to be visible to all attendees.
Checking this box will display your presense on the attendees list, view your profile and allow other attendees to contact you via 1-1 chat. Read the Privacy Policy. At any time, you can choose to disable this preference.
Select your Interests!
add
Upload your photo
Uploading..
OR
Connect via Twitter
Connect via Linkedin
EDIT PASSWORD
Share
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Sign in to gain access to Spark Summit 2017 | San Francisco
Please sign in with LinkedIn to continue to Spark Summit 2017 | San Francisco. Signing in with LinkedIn ensures a professional environment.
Are you sure you want to remove access rights for this user?
Details
Manage Access
email address
Community Invitation
Matthew Hunt | Spark Summit 2017
Matthew Hunt, Bloomberg, at Spark Summit 2017
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/25/could-apache-spark-become-a-universal-computation-engine-sparksummit/
Could Apache Spark become a universal computation engine?
Spark Summit keynotes are known for their surprises, and this year the stand-out changes were in data streaming, with sub-millisecond times predicted for some workloads. With multiple avenues open for potential success, the community is watching as Spark matures to fulfill the promise of what it could be: But does that promise include becoming a database?
Exploring the gap between theoretical possibilities and reality, Matthew Hunt (pictured) technologist at Bloomberg LP, discussed the maturation of Spark with George Gilbert (@ggilbert41) and David Goad (@davidgoad), co-hosts of theCUBE, SiliconANGLE Media’s mobile livestreaming studio, during this year’s Spark Summit event in San Francisco, California.
As a pioneer of streaming media, Bloomberg has a long history developing apps for news and finance and has developed its own relational database, ComDB2. “Everyone needs a database,” Hunt said, adding that most companies do not have the resources to develop their own. This leads to the question: Can Spark become a database?
Hunt believes that Spark has the promise to become a Universal Computation Engine. Describing a universal system as having distributed file store, database with transactional semantics, extensible analytics and the ability to stream data in, he asked, “how close can you come to that?”
Maturity means real-world use
Although the dream might be a universal system, the more practical question is how to make Spark and other databases work well together.
“If you have to master 5,000 skills and 200 different products, that’s a huge impediment for real-world usage,” said Hunt, who sees practical usage coalescing around a smaller set of options.
Hunt predicted that Apache Arrow, which powers columnar in-memory analytics, is about to explode because “it lets you connect these systems radically more efficiently in a standardized way.”
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)