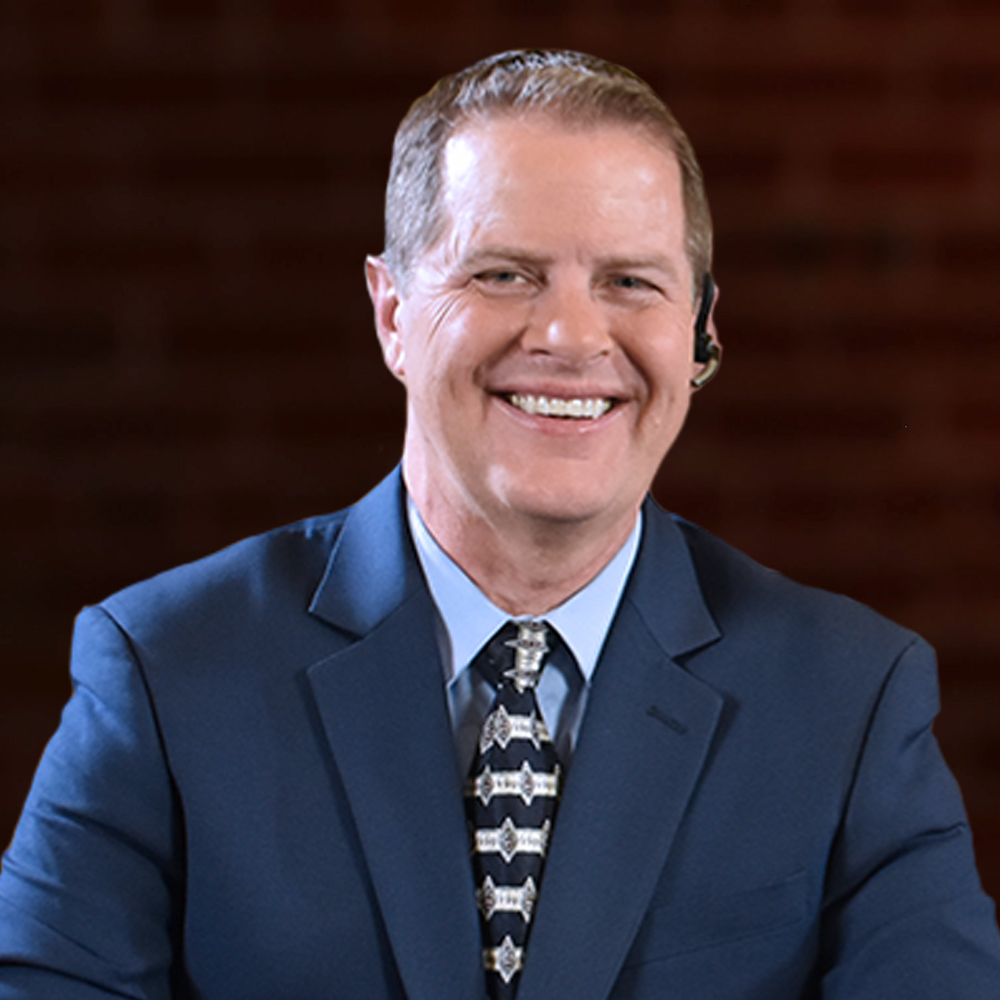
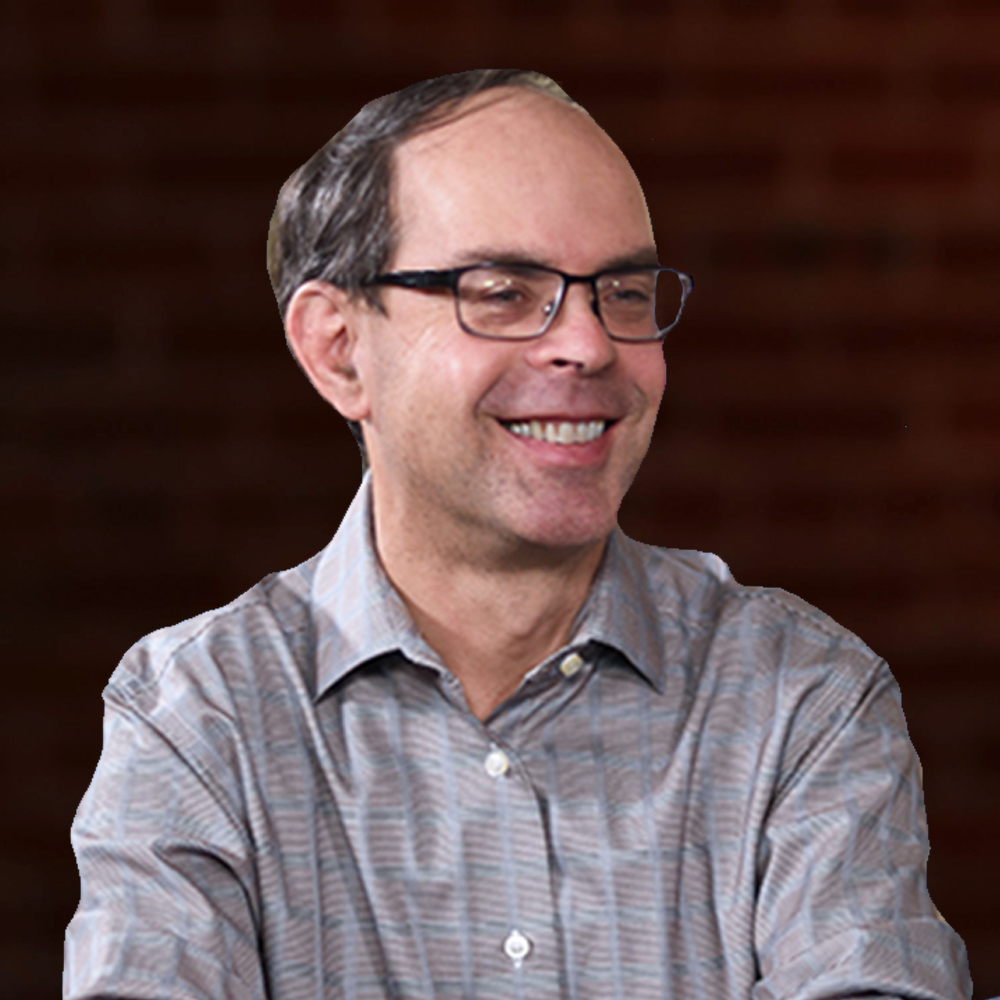
Ash Munshi from Pepperdata CUBE hosts David Goad & George Gilbert are live from Spark Summit 2017 at the Moscone West in San Francisco CA
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/20/can-big-data-devops-see-what-abstraction-is-hiding-sparksummit/
Can big data DevOps see what abstraction is hiding?
DevOps that have worked well in other areas of information technology can’t hack it in big data, according to Ash Munshi (pictured), chief executive officer of Pepperdata Inc.
“While agile and all that still works, the tools don’t work,” Munshi said in an interview at this year’s Spark Summit in San Francisco, California.
Tightening the loop leading from development to operations is trickier due to the mass of data in the middle and the number of machines computing it, Munshi told David Goad (@davidgoad) and George Gilbert (@ggilbert41), co-hosts of theCUBE, SiliconANGLE Media’s mobile live streaming studio. (* Disclosure below.)
There could be thousands of machines working to solve one problem. This obviously points to infrastructure abstraction and virtualization as possible fixes, but, by themselves, they’re half-baked solutions, Munshi stated.
Apache Spark’s data engine abstracts the paradigm developers write against, which is wonderful, Munshi explained, since it simplifies the code-writing process.
“The problem when you abstract is, what does that abstraction do down in the hardware, and where am I losing performance?” he said.
Spark’s user interface provides some information about processor and memory resource consumption and the state of the garbage collector, Munshi stated. “What it doesn’t do is give you a time-series view of what’s going on,” he said.
Visibility ties up loose ends?
With blow-by-blow visibility, Pepperdata’s recently announced Code Analyzer for Apache Spark allows users to pinpoint performance issues in their code. A second, complementary Pepperdata release is the Application Profiler. This tool analyzes all data from completed applications in the Spark History Server. If it discovers faulty executors, it highlights them so developers can click on them for explanations and suggested cures.
Pepperdata customers have discovered that this is a useful prognosticator as well, Munshi stated.
“If the Application Profiler comes back and says, ‘Everything is green; there’s no critical issues there,’ then they’re saying, ‘OK, fine. Put it on the production cluster,'” he said.
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Register For Spark Summit 2017 | San Francisco
Please fill out the information below. You will recieve an email with a verification link confirming your registration. Click the link to automatically sign into the site.
You’re almost there!
We just sent you a verification email. Please click the verification button in the email. Once your email address is verified, you will have full access to all event content for Spark Summit 2017 | San Francisco.
I want my badge and interests to be visible to all attendees.
Checking this box will display your presense on the attendees list, view your profile and allow other attendees to contact you via 1-1 chat. Read the Privacy Policy. At any time, you can choose to disable this preference.
Select your Interests!
add
Upload your photo
Uploading..
OR
Connect via Twitter
Connect via Linkedin
EDIT PASSWORD
Share
Forgot Password
Almost there!
We just sent you a verification email. Please verify your account to gain access to
Spark Summit 2017 | San Francisco. If you don’t think you received an email check your
spam folder.
In order to sign in, enter the email address you used to registered for the event. Once completed, you will receive an email with a verification link. Open this link to automatically sign into the site.
Sign in to gain access to Spark Summit 2017 | San Francisco
Please sign in with LinkedIn to continue to Spark Summit 2017 | San Francisco. Signing in with LinkedIn ensures a professional environment.
Are you sure you want to remove access rights for this user?
Details
Manage Access
email address
Community Invitation
Ash Munshi | Spark Summit 2017
Ash Munshi from Pepperdata CUBE hosts David Goad & George Gilbert are live from Spark Summit 2017 at the Moscone West in San Francisco CA
#SparkSummit #theCUBE
https://siliconangle.com/2017/07/20/can-big-data-devops-see-what-abstraction-is-hiding-sparksummit/
Can big data DevOps see what abstraction is hiding?
DevOps that have worked well in other areas of information technology can’t hack it in big data, according to Ash Munshi (pictured), chief executive officer of Pepperdata Inc.
“While agile and all that still works, the tools don’t work,” Munshi said in an interview at this year’s Spark Summit in San Francisco, California.
Tightening the loop leading from development to operations is trickier due to the mass of data in the middle and the number of machines computing it, Munshi told David Goad (@davidgoad) and George Gilbert (@ggilbert41), co-hosts of theCUBE, SiliconANGLE Media’s mobile live streaming studio. (* Disclosure below.)
There could be thousands of machines working to solve one problem. This obviously points to infrastructure abstraction and virtualization as possible fixes, but, by themselves, they’re half-baked solutions, Munshi stated.
Apache Spark’s data engine abstracts the paradigm developers write against, which is wonderful, Munshi explained, since it simplifies the code-writing process.
“The problem when you abstract is, what does that abstraction do down in the hardware, and where am I losing performance?” he said.
Spark’s user interface provides some information about processor and memory resource consumption and the state of the garbage collector, Munshi stated. “What it doesn’t do is give you a time-series view of what’s going on,” he said.
Visibility ties up loose ends?
With blow-by-blow visibility, Pepperdata’s recently announced Code Analyzer for Apache Spark allows users to pinpoint performance issues in their code. A second, complementary Pepperdata release is the Application Profiler. This tool analyzes all data from completed applications in the Spark History Server. If it discovers faulty executors, it highlights them so developers can click on them for explanations and suggested cures.
Pepperdata customers have discovered that this is a useful prognosticator as well, Munshi stated.
“If the Application Profiler comes back and says, ‘Everything is green; there’s no critical issues there,’ then they’re saying, ‘OK, fine. Put it on the production cluster,'” he said.
Watch the complete video interview below, and be sure to check out more of SiliconANGLE’s and theCUBE’s coverage of Spark Summit 2017. (* Disclosure: DataBricks Inc. sponsored this Spark Summit 2017 segment on SiliconANGLE Media’s theCUBE. Neither DataBricks nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)